An outlier in statistics is an observation that falls significantly outside the typical range of your dataset, usually defined as any data point more than 1.5 times the interquartile range (IQR) below the first quartile or above the third quartile. These unusual values stand apart from the majority of your data, often signaling measurement errors, data entry mistakes, or genuinely exceptional cases that deserve closer attention.
For K-12 educators, recognizing outliers is more than a mathematical statistics exercise. It’s a practical skill that helps you spot students who need intervention, identify assessment questions that may be flawed, and teach data literacy in ways students can actually apply. When you’re analyzing test scores, attendance patterns, or reading progress, outliers tell stories: the student who suddenly missed 15 days in a month, the quiz question every high performer got wrong, or the fifth grader reading at a tenth-grade level.
This guide walks you through what outliers are, how to identify them using the widely accepted 1.5 × IQR rule and other detection methods, the different types you’ll encounter, and how to apply this knowledge in your classroom and school data work. You’ll gain confidence interpreting your own datasets and helping students understand why that one unusually high or low number matters.
What an Outlier Means in Statistics
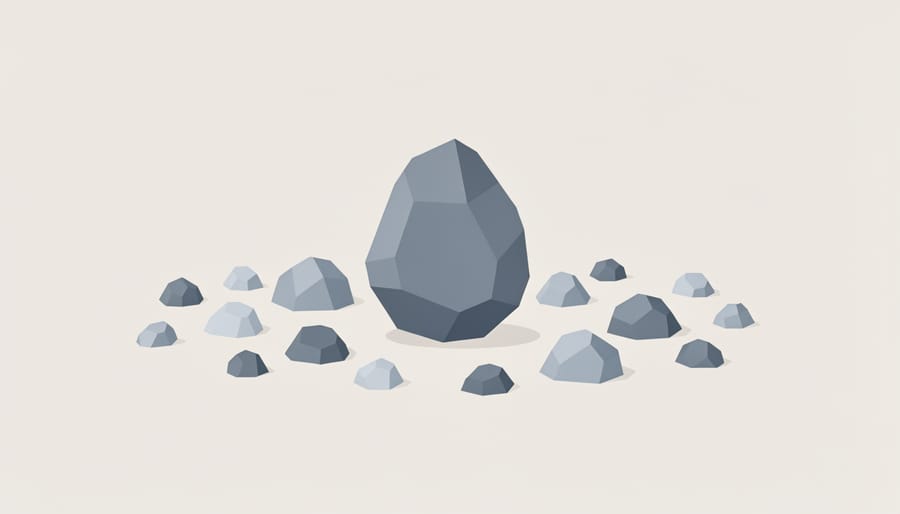
An outlier is a data point that differs significantly from the other observations in a dataset. Instead of clustering with the majority of values, an outlier stands alone at the extreme high or low end of the range.
When you analyze classroom data, most values naturally group together. If you record your students’ quiz scores, you might see most results falling between 70 and 90 points. An outlier would be a score like 15 or 100, values that sit far outside where most students landed. The same pattern appears in attendance data: if nearly all students miss between zero and three days per semester, a student absent for twenty days represents an outlier worth investigating.
- Outlier
- A data point that falls far outside the typical range of a dataset, standing apart from the majority of observations.
- Dataset
- A collection of related measurements or observations gathered for analysis, such as all test scores from a single class.
- Typical Range
- The span where most data points cluster, representing normal or expected values in the dataset.
- Extreme Value
- A measurement that sits at the far high or low end of the distribution, potentially qualifying as an outlier.
Understanding what makes a value an outlier matters because these unusual observations can signal something important. An extremely low test score might indicate a student struggling with the material, while an unusually high number of library book checkouts could highlight an engaged reader who needs advanced materials. Outliers deserve attention precisely because they break the pattern, they often represent students, situations, or conditions that need a different response than the typical approach.
Rather than viewing outliers as problems or errors to discard, educators can treat them as flags that prompt deeper investigation. The student data point that stands apart from the rest often tells the most important story about individual needs and opportunities for targeted support.
How Outlier Detection Works
The 1.5 × IQR Rule
The 1.5×IQR outlier rule gives you a straightforward, mathematical way to draw boundaries around what counts as typical in your dataset. Think of it as creating a fence: data points inside the fence are normal, and anything outside deserves a closer look.
Start by finding the quartiles. Quartiles divide your data into four equal parts when arranged from smallest to largest. The first quartile (Q1) marks the 25th percentile, one-quarter of your values fall below it. The third quartile (Q3) sits at the 75th percentile, where three-quarters of the data falls below. The middle 50% of your data lives between these two points.
The interquartile range (IQR) measures the spread of that middle half. Calculate it by subtracting Q1 from Q3. If your class’s test scores have Q1 at 72 and Q3 at 88, the IQR is 16 points. This range tells you how much variability exists in the core group of students.
Now apply the 1.5 multiplier. Multiply your IQR by 1.5, then use that result to set lower and upper boundaries. The lower fence sits at Q1 minus 1.5 times the IQR. The upper fence sits at Q3 plus 1.5 times the IQR. Using our test score example with an IQR of 16, multiply 16 by 1.5 to get 24. The lower boundary becomes 72 minus 24, which equals 48. The upper boundary is 88 plus 24, or 112.
Any score below 48 or above 112 flags as an outlier. A student who scored 35 would fall outside the lower fence, suggesting either a struggle that needs intervention or possibly a grading error. A score of 98 sits comfortably within bounds, high, but not statistically unusual for this group.
The beauty of this method lies in its objectivity. You’re not guessing what seems extreme; the data itself defines the boundaries based on its own spread. Students can follow these steps with a calculator, making it an excellent introduction to statistical thinking in middle and high school classrooms.
Other Detection Techniques
Beyond the 1.5 × IQR rule, educators may come across several other outlier detection methods, especially when working with technology tools or collaborating with data specialists. Understanding what these methods do can help you make informed decisions about which tools to use and how to interpret their results.
The Z-score method measures how many standard deviations a data point sits from the mean. If a student’s test score has a Z-score of +2.5, it means the score is 2.5 standard deviations above the average. Most implementations flag values beyond a z-score threshold near 3 as outliers. This approach works well when your data follows a normal distribution, such as standardized test results across large student populations.
DBSCAN (Density-Based Spatial Clustering of Applications with Noise) identifies outliers by looking for data points that sit in low-density regions, isolated from clusters of similar values. This technique excels at finding unusual patterns in multi-dimensional data, though it requires more computational power and setup knowledge than simpler methods.
The isolation forest method treats outliers as observations that are easier to isolate from the rest of the dataset. It works by randomly splitting data until individual points separate out, on the theory that outliers require fewer splits to isolate. This machine learning approach handles complex datasets effectively but requires specialized software.
The numeric outlier technique applies the same IQR logic you learned earlier but allows you to adjust the multiplier (the k value in the formula) based on your specific needs. You might use 1.5 for general screening or tighten to 1.0 when seeking more sensitive detection.
For most K-12 classroom applications, the 1.5 × IQR method remains the most practical choice. It requires only basic calculations, produces results students can verify by hand, and doesn’t assume any particular data distribution shape.
Types of Outliers and What Causes Them
Not all outliers mean the same thing. Some signal problems that need fixing, while others reflect genuine extremes worth preserving. Understanding the difference helps you make smart decisions about your data rather than automatically deleting anything unusual.
Outliers fall into three main categories based on their origin. Measurement errors occur when data gets recorded incorrectly, a thermometer reading 150°F in a classroom, for instance, or a student height logged as 7 feet tall. These are mistakes in capturing information, not real phenomena. Data entry mistakes happen when correct measurements get typed wrong: a test score of 95 entered as 59, or an attendance count of 3 recorded as 30. Both types represent flawed data that should be corrected or removed once identified.
The third category matters most: legitimate outliers that accurately represent unusual but real conditions. A student genuinely scoring 100% when classmates average 70%, or a typically quiet class having zero behavior incidents when the school average is five per week. These outliers tell you something meaningful about individual variation or exceptional circumstances. They shouldn’t be discarded just because they’re extreme.
Common sources of outliers in educational settings include:
- Recording errors from misread instruments, switched columns, or misheard verbal reports
- Unusual student circumstances like extended illness, family crisis, or recent enrollment mid-year
- Assessment anomalies such as different test versions, modified accommodations, or technical glitches during digital testing
- Authentic exceptional performance reflecting true talent, extensive preparation, or accelerated learning
Your response to an outlier depends on its cause. Investigate values that seem physically impossible or inconsistent with other known information, these likely need correction. You can fix wrong data once you’ve confirmed the error source. But when an outlier represents a real student’s authentic experience, preserve it. That exceptional reading level or concerning absence pattern might signal exactly the student who needs targeted support or enrichment. The outlier isn’t corrupting your analysis; it’s highlighting someone who deserves attention.
How Educators Use Outlier Detection
Outlier detection helps you move beyond averages to see the students who need your attention most. When you analyze classroom data with outliers in mind, you spot patterns that summary statistics hide and create opportunities to support every learner.
Student Assessment Analysis
Test scores offer clear examples of meaningful outliers. A student who scores significantly below the class range might need immediate intervention, while one scoring well above could benefit from enrichment opportunities. Rather than filtering these scores out, data-driven instruction treats them as signals pointing you toward students who require differentiated support. The same 1.5 × IQR approach you’d use on any dataset shows you which performances fall outside typical bounds, helping you identify learning gaps or advanced readiness you might otherwise miss.
Attendance and Engagement Tracking
Attendance outliers reveal students at risk. Someone with unusually low attendance compared to classmates faces academic challenges that extend beyond curriculum gaps. When you track participation metrics or assignment completion rates, students at the extremes tell important stories. A sudden drop in a normally engaged student’s participation merits investigation. A pattern of consistently low engagement across multiple metrics identifies students who need relationship-building or motivation strategies.
Behavior Monitoring
Discipline referrals, classroom disruptions, or positive behavior recognitions create datasets where outliers matter. Students with significantly higher or lower behavior incident counts than peers deserve individualized attention. The outlier isn’t the problem to eliminate; it’s the student to understand and support differently.
Resource Allocation Decisions
School administrators use outlier analysis when distributing supports. Which classrooms show unusual supply requests? Which teachers report significantly different student needs? Real-time data about resource usage helps you redirect materials, personnel, or professional development to where the extremes indicate greatest need.
The goal isn’t removing outliers from your datasets. It’s recognizing them as students whose unique circumstances require your most thoughtful, individualized response.
Frequently Asked Questions
How do you detect outliers?
The most common approach is the 1.5 × IQR rule, which identifies any data point falling more than 1.5 interquartile ranges below the first quartile or above the third quartile. This method works well for classroom datasets and doesn’t require assumptions about how your data is distributed.
What is the 1.5×IQR rule?
The 1.5×IQR rule defines outliers as observations below Q1 − 1.5 IQR or above Q3 + 1.5 IQR, where IQR is the interquartile range (the difference between the third and first quartiles). This creates clear mathematical boundaries that help you objectively identify which data points are unusually extreme.
Can you detect outliers using Z-score and IQR only when data is normally distributed?
The IQR method works with any data distribution, making it versatile for classroom use where student data rarely follows a perfect bell curve. The Z-score method, however, assumes normally distributed data, so it’s less reliable when working with skewed test scores or attendance patterns.
What statistical test can be used to identify outliers in non-normal data distributions?
For non-normal distributions, the numeric outlier technique (based on IQR), DBSCAN technique, and isolation forest method all work effectively. The IQR-based approach remains the most accessible for educators since it requires only basic quartile calculations and no specialized software.
These questions reflect the real concerns teachers face when analyzing student data. You might encounter skewed grade distributions, attendance records with seasonal patterns, or behavioral data that doesn’t follow a neat bell curve. Understanding which detection method suits your specific dataset helps you avoid misidentifying normal variation as problematic outliers or missing genuinely unusual cases that warrant attention. When you’re uncertain about your data’s distribution, starting with the IQR method gives you a reliable foundation that works across different situations without requiring statistical expertise beyond basic concepts your students can grasp.
Understanding outliers transforms how you approach classroom data. Rather than viewing unusual values as problems to discard, treat them as signals worth investigating. That outlier test score might reveal a struggling student who needs support or a gifted learner ready for enrichment. The attendance pattern that stands apart could indicate a family crisis requiring intervention.
Outlier detection strengthens your ability to make evidence-based decisions about instruction, assessment, and student support. It also offers a powerful teaching opportunity, showing students how to think critically about data, question assumptions, and recognize when numbers tell important stories.
Share your outlier detection strategies and classroom applications in our community forums, where educators exchange practical approaches to data analysis. Explore our interactive tools to practice identifying outliers in sample datasets and develop confidence applying these techniques to your own classroom data. Every outlier represents a chance to better understand and serve your students.